Server failures behind global Microsoft 365 outage, says company

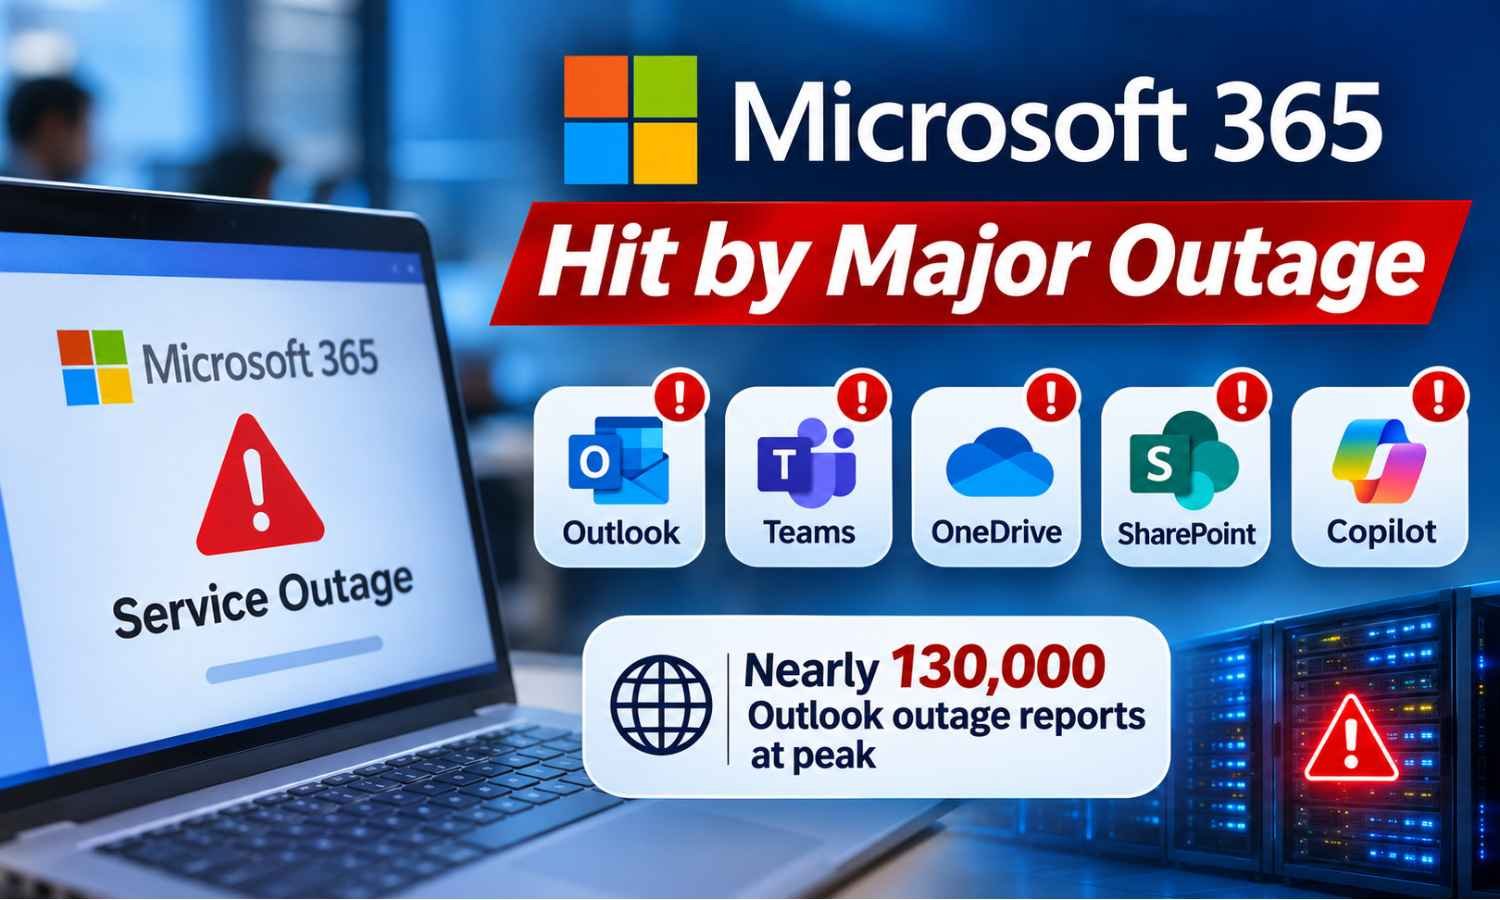
Hyderabad: A Microsoft 365 outage on Thursday cut off hundreds of thousands of users in several regions from their mail, chat, stored files and AI tools. Microsoft said the cause lay inside its own servers rather than a jump in traffic.
The trouble started in the Americas and then spread wider. According to the company, internal server failures drove the disruption.
Outage-tracking site Downdetector logged nearly 130,000 user reports for Outlook at the peak, just after 1 p.m. Eastern Time. Microsoft 365 drew tens of thousands more, and Teams, Copilot, OneDrive and SharePoint also recorded sharp rises. At one stage, close to 20,000 reports a minute came in from dozens of countries.
Report numbers fell once Microsoft began rolling out fixes. Even so, many users still could not send or receive mail or open their inboxes through the afternoon and into the evening.
Failed health checks behind Microsoft 365 outage
Microsoft tracked the problem under incident ID EX1550543 for Exchange Online and MO1550821 for the wider Microsoft 365 suite. Its advisories named Exchange Online, Microsoft Teams, SharePoint Online, Microsoft 365 Copilot and Microsoft Defender XDR among the services that could be affected. The company said users in any region could run into connection problems.
Updates on the Microsoft 365 Status account and the admin center traced the fault step by step. Engineers first reported unusually high load in parts of the infrastructure. They then found that user traffic had not gone up.
Instead, many servers had unexpectedly dropped out of service once they failed automated health checks. That left the remaining servers to carry normal demand by themselves, which led to strain and connectivity errors.
Microsoft said the failed checks appeared to be tied to a particular component that processes server health. It tested a different health-check method, which brought some of the affected servers back, and started extending that change. The company also paused deployments, moved traffic between parts of its global network and began restarting servers that had stopped responding.
According to later updates, one core process had been overloaded on some servers, adding to the capacity loss. Microsoft said it had not found any recent change linked to the start of the problem.
AWS says its systems ran normally during disruption
Microsoft services dominated Downdetector’s most-reported list, including Outlook, Microsoft 365, Copilot, Teams, OneDrive, the Microsoft Store, Xbox Network and Microsoft Account. Gmail, Google, Amazon Web Services, Facebook, Zoom and Cloudflare also appeared further down.
Such secondary spikes are common in large outages, as users check whether other services are down or hit problems with tools that connect to Microsoft 365. Amazon Web Services said its systems were working normally and that some reports seemed to trace back to the separate Microsoft problem. Google Cloud status pages showed no similar issues.
Smaller reports also surfaced for Blizzard Battle.net and Overwatch, but these had no link to the Microsoft incident and stayed limited.
By late Thursday, Microsoft said some servers hit by the Microsoft 365 outage were back in service and that it was widening its recovery work. Full service had not yet returned, and the company gave no firm timeline. Microsoft directed administrators to the Microsoft 365 admin center and status.cloud.microsoft for updates.
